
AI Agent Web Access API
Choose an integration
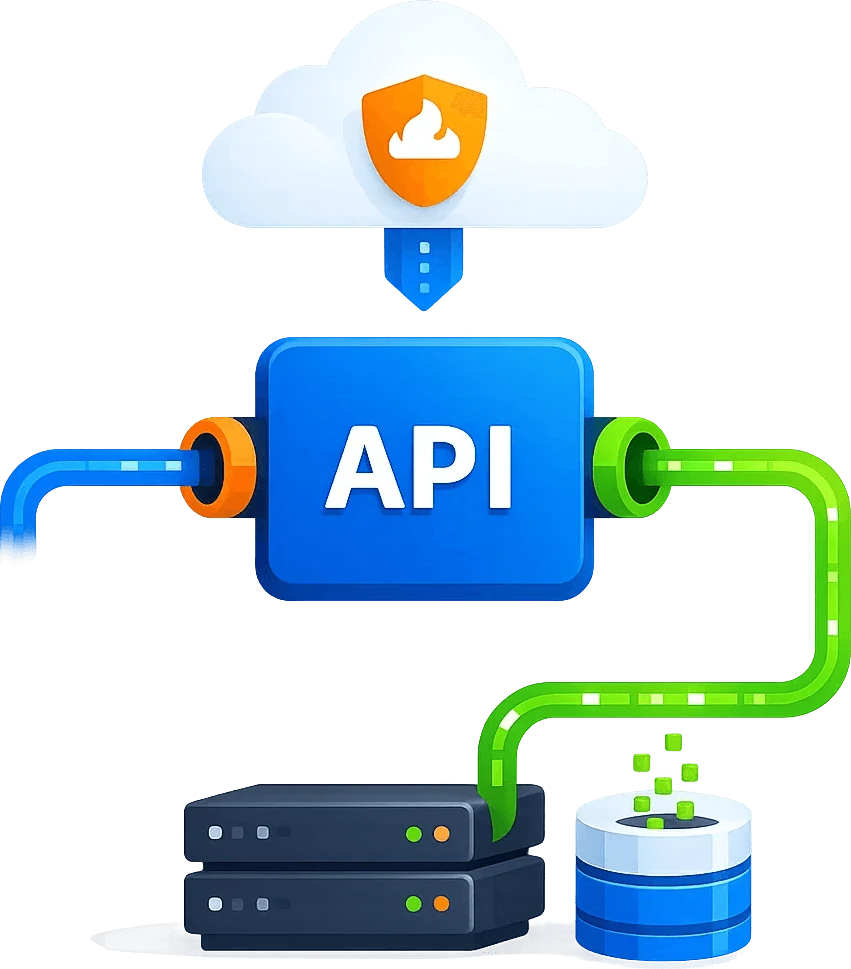
The API handles HTTP requests and responses. Browser rendering, screenshots, extraction, pagination and storage belong to your own tools or project workflow.
Prepare the runtime
Keep tool approvals enabled. Never put credentials in chat or browser code.
Inspect the response
Inspect x-cb-status, HTTP status and actual business content after the request.
Connect Codex to the API. Keep credentials in secure configuration and prepare one read-only request.
Read CLOUDBYPASS_APIKEY, set x-cb-host and check the runtime that sends the request.
Example not executed. Configure credentials and an authorized target first.curl --include --request GET \
"https://api.cloudbypass.com/" \
--header "x-cb-host: example.com" \
--header "x-cb-apikey: ${CLOUDBYPASS_APIKEY:?}" \
--max-time 90Inspect x-cb-status, HTTP status and actual business content after the request.
curl --include --request GET \
  "https://api.cloudbypass.com/" \
  --header "x-cb-host: example.com" \
  --header "x-cb-apikey: ${CLOUDBYPASS_APIKEY:?}" \
--max-time 90Example not executed. Configure credentials and an authorized target first.
Cloudflare challenge handling
Give AI agents a stable web access layer for live pages and structured output
AI agents need reliable access to live webpages, dynamic content, overseas sites and public pages that may return 403 or challenge flows. Scrapingbypass packages web access, regional environments, browser rendering, screenshots, Markdown, JSON and logs into callable API capabilities for agent workflows.
Configure sessions for the task
Check the region, proxy IP and request settings, and keep the session consistent with the target’s requirements.
Validate the response
Check both the status code and response body before passing the result to your existing parser.
Challenge handling
Keep Cloudflare handling and supported DataDome workflows in one access layer, with clear failure diagnostics.
IP rotation and sessions
Use rotating residential or datacenter IPs, sticky sessions and bounded retries for ongoing monitoring.
Regional access
Choose proxy locations by country, city and task.
Status logs and compliance
Keep status codes, screenshots and failure details for auditing.
Cloudflare / Turnstile / WAF
Move AI agents from “can write code” to “can reliably access webpages”
Expose Cloudflare handling, confirmed DataDome workflows, regional access and validated page output as reusable agent capabilities.
STEP 01
Agent tool calls
Access pages through APIs or tool functions and avoid repeated challenge and retry logic in scripts.
STEP 02
Cloudflare and DataDome access workflows
Handle JS Challenge, Turnstile, WAF and 403 failures on public or authorized pages.
STEP 03
Structured output
Return HTML, Markdown, JSON, screenshots and status for agents, RAG or workflow tools.
STEP 04
Logs and audit
Record URL, region, status code, failure reason and task evidence for review.
Use Cases
Typical applications for AI Agent Web Access API
For AI agents, AI browsers, research assistants, sales assistants and automation workflows, covering business scenarios from one-off access to long-term monitoring.
AI research assistants
Build stable access, geo verification, screenshot evidence and structured results around AI research assistants, reducing manual checks and duplicate script maintenance.
AI browsers and web agents
Build stable access, geo verification, screenshot evidence and structured results around AI browsers and web agents, reducing manual checks and duplicate script maintenance.
AI sales and market assistants
Build stable access, geo verification, screenshot evidence and structured results around AI sales and market assistants, reducing manual checks and duplicate script maintenance.
AI workflow automation
Build stable access, geo verification, screenshot evidence and structured results around AI workflow automation, reducing manual checks and duplicate script maintenance.
Multi-region page checks
Build stable access, geo verification, screenshot evidence and structured results around Multi-region page checks, reducing manual checks and duplicate script maintenance.
Implementation steps
Connect the Scrapingbypass access layer in 4 steps
Start with one high-value page or task, validate access, then expand into scheduled workflows.
01. Define the access target
Confirm URL, region, frequency, output format and business boundary.
02. Choose an access strategy
Select API, rendering, screenshots, dynamic IP, sticky session or retry strategy. Cloudflare and DataDome share the same API integration logic and request code.
03. Connect business systems
Send results to crawlers, AI agents, workflows, QA or internal monitoring systems. Integrate your tested request code into the application. Cloudflare and DataDome share the same API integration and call pattern. Validate response status and content before parsing, pagination or automation.
04. Review and optimize
Track status codes, failure reasons, screenshots and logs to keep access stable. Cloudflare and DataDome share one API credit balance, consumption rules and pricing. Choose a plan based on your usage; proxy traffic is billed separately.
FAQ
Common questions
How is this different from a normal proxy?
A normal proxy mainly provides an exit. Scrapingbypass focuses on the full access workflow: regional environment, dynamic pages, challenge handling, screenshots, structured output, retries and logs.
Is it suitable for non-developers and AI coding users?
Yes. Teams can build the business logic with templates, workflow tools or AI-generated code, then hand protected web access to the Scrapingbypass API.
How should compliance risk be controlled?
Use it for public data, authorized data and legitimate business workflows. Add domain allowlists, rate limits, task logs and human review where needed.