Coupon and promotion monitoring across Cloudflare and DataDome targets
Keep coupon codes, expiry dates and campaign pages current without maintaining verification logic in every collector. Combine Cloudflare challenge handling with the DataDome slider and puzzle CAPTCHA workflow for supported promotion targets. Regional sessions and response checks help you save the actual offer, not a verification screen, during busy campaign periods.
Start Free Trial API DOCs Code generator

Why Coupon & Promotion Data Scraping Is Hard
Why Is Coupon & Promotion Data Scraping So Unstable?
Promotion flows change quickly, anti-bot defenses keep getting tougher, and page structures are often complex. A scraping system doesn't just need to "access the page" - it must collect data reliably, completely, and accurately. Otherwise, delayed or missing data can directly impact marketing decisions, pricing strategies, and conversion performance.
-
Cloudflare Verification Triggers Too Often
The JS challenge and verification pages block requests, causing large-scale scraping jobs to fail or time out.
-
Frequent Page Changes Break Parsers
Layout updates and field replacements happen constantly, pushing maintenance costs higher and higher as your system scales over time.
-
Hidden Coupons & Benefit Entrances Are Hard to Detect
Deep entry points, complex parameters, and long redirect chains lead to incomplete coupon codes and rules extraction.
-
High-Concurrency Scraping Gets Rate-Limited
Burst traffic triggers risk controls and throttling, limiting IP access and causing data gaps over time.
Technical Support Contact
Turn Verification Blocks into Clean, Usable Coupon & Promotion Data with Scrapingbypass API
Use Cloudflare verification handling and a confirmed DataDome solver integration alongside scheduled collection. Check offer text, currency and expiry dates before comparing discounts or notifying users.
-
Automatic 5-Second Challenge Handling
No manual steps required. Reliably passes challenge pages to improve success rates for coupon sites, promo hubs, and deal landing pages.
-
JavaScript Challenge Support
Executes dynamic challenge logic and returns parse-ready content, reducing empty pages, 403 errors, and common aggressive anti-bot script-based blocking.
-
Configurable Request Parameters
Customize UA, headers, referer rules, and more to mimic real user traffic patterns and lower your risk of triggering anti-bot defenses.
-
Stable High-Concurrency Data Delivery
Designed for bulk scraping and recurring monitoring. Schedule tasks and keep data flowing reliably for growth-focused operations.
Use Cases
Built for Websites That Require Bypassing Cloudflare Verification to Collect Coupon & Promotion Data Reliably
Ecommerce Coupon Hub Aggregation & Monitoring
Collect data from coupon hub entry points, category bundles, platform perks, and membership coupons. Automatically handles challenge verification and supports continuous monitoring - ideal for deal discovery platforms, cashback tools, and internal promotion dashboards that require long-term data accuracy.
Promo Event Pages & Channel Tracking
Track fast-changing pages like major campaign hubs, flash-sale channels, and limited-time sections. Supports scheduled scraping and layout-change adaptation to avoid blind spots caused by verification blocks - helping operations teams stay on top of campaign cadence and placement changes.
Hidden Coupons & Deep-Link Benefit Parsing
Built for multi-redirect flows, buried coupon codes, and complex benefit rules. Supports path-based tracking with clean content returns - improving coupon completeness for post-coupon price calculations and recommendation ranking engines.
Real-Time Price & Post-Coupon Price Volatility
For price-sensitive workflows, capture promo-period price changes and post-coupon cost trends. Stable request execution reduces interruptions - enabling price-drop alerts, inventory-based triggers, and smarter campaign bidding adjustments.
Competitive Promotion Intelligence Collection
Continuously monitor competitors' campaign frequency, discount intensity, and landing-page layout changes to build a comparable promotion intelligence library. Cloudflare bypass support improves coverage and reduces missing data during critical moments.
Cross-Site Deal Aggregation & Recommendation Feeds
Aggregate promotion content across multiple sites, regions, and languages, then output standardized, usable data for content distribution and recommendation systems. With reliable challenge handling and stable responses, you improve aggregation efficiency and data consistency at scale.
Scrapingbypass Onboarding Workflow
1.Create Your Account
Register a Scrapingbypass API account - Sign Up Now
Register a Scrapingbypass Proxy account - Sign Up Now
One account gives you API and proxy access. Log in within 30 days and open Trial Activity from the gift icon to claim trial credits and traffic.
2.Test with the Code Generator
Use the Code Generator to configure and test Cloudflare or DataDome requests. Both use the same integration logic and request code. Keep the proxy IP, cookies and session consistent.
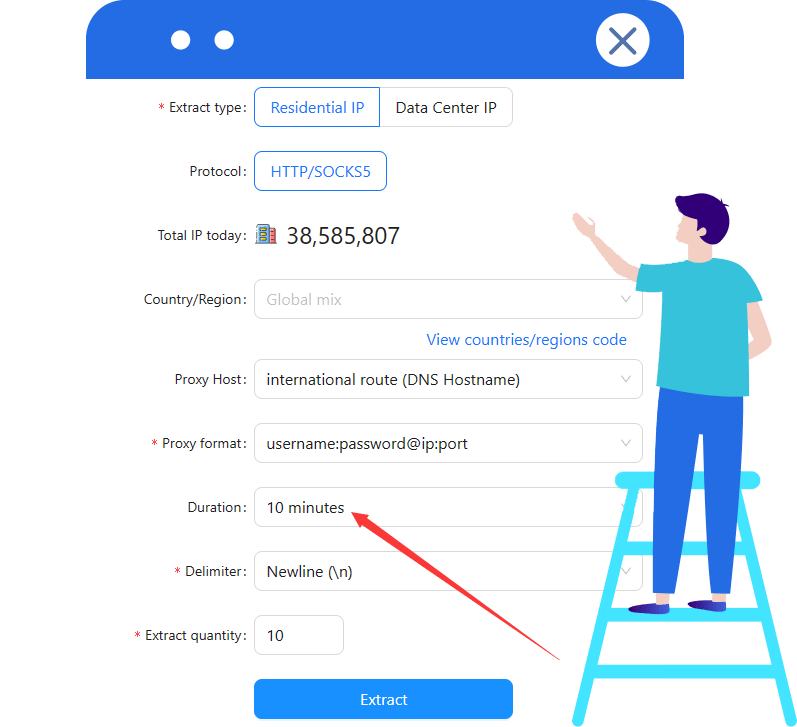
V1 includes a rotating proxy. V2(s) requires a stable proxy IP; configure a sticky session of at least 10 minutes when using Scrapingbypass rotating proxies.
For assistance, see the API documentation or contact Scrapingbypass Support.
3.Integrate the Scrapingbypass API
Integrate your tested request code into the application. Cloudflare and DataDome share the same API integration and call pattern. Validate response status and content before parsing, pagination or automation.
4.Select a Pricing Plan
After testing, choose a plan based on your usage. Cloudflare and DataDome share the same API credits, consumption rules and pricing. View Pricing
For proxy traffic, select a Rotating Datacenter or Rotating Residential proxy plan.
Cloudflare and DataDome challenge handling consume API credits; some workflows also need a proxy. API credits and proxy traffic are billed separately. A proxy connection does not replace CAPTCHA handling.

Scrapingbypass API Pricing
Test target compatibility, then choose an API plan for your workload
Each successful request costs 1 credit. Successful V2(s) verification costs 2 extra credits, not refunded if the later response fails. Proxy traffic is billed separately.
Basic Plan
-
$49
-
Credits:80000Validity:30 DaysSpeed:20 req/s
Standard Plan
-
$79
-
Credits:300000Validity:30 DaysSpeed:20 req/s
Advanced Plan
-
$129
-
Credits:1000000Validity:30 DaysSpeed:25 req/s
Pro Plan
-
$259
-
Credits:2200000Validity:30 DaysSpeed:25 req/s
Premium Plan
-
$489
-
Credits:4600000Validity:30 DaysSpeed:30 req/s
-
Best Value
Ultimate Plan
-
$1056
-
Credits:12000000Validity:30 DaysSpeed:30 req/s
Need more credits than the standard plans provide? Get a custom plan tailored to your workload Unlimited credits / Dedicated servers / Higher concurrency / Priority technical support
Contact Us for a Custom Plan Buy Rotating IPsFAQFrequently Asked Questions
Why do I keep running into Cloudflare challenges when scraping coupon and promotion data?
Coupon hubs and promo landing pages are high-value targets with heavy traffic and strong automation signals, so they're more likely to trigger Cloudflare protections like the 5-second check, JavaScript Challenges, or Turnstile. This often results in blocked requests or challenge pages instead of real content. Scrapingbypass API handles these challenges automatically and returns usable page data.
What types of Cloudflare verification can Scrapingbypass API handle?
Scrapingbypass API reliably handles common Cloudflare protections including the 5-second check (JavaScript Challenge), JS challenges, and Turnstile, helping reduce data loss caused by 403 errors or challenge pages.
Coupon pages change frequently. How can I reduce the maintenance cost of scraping rules?
A practical approach is "entry-point tracking + structured parsing templates + incremental validation." Combine that with Scrapingbypass API to ensure pages load consistently, so your team can focus on parsing and data modeling - not fighting verification blocks.
Scraping coupon data often requires high concurrency. How do I avoid rate limits and bans?
For high-concurrency workloads, use task layering, pacing control, and realistic request fingerprints (UA/Headers/Referer, etc.). Scrapingbypass API supports configurable request parameters and scalable concurrency to significantly improve success rate and stability at scale.
What output formats does Scrapingbypass API return? Is it suitable for automation pipelines?
Scrapingbypass API can return the raw HTML of the target page for easy parsing, cleaning, and structuring on your backend. It also supports both HTML and JSON workflows, making it simple to integrate into automation pipelines across multiple languages.
Does Scrapingbypass API "auto-click" CAPTCHAs? How should I implement my scraper logic?
Scrapingbypass API works by taking your request, fetching the page through our access layer, and minimizing Cloudflare challenges so you can retrieve the actual content. Your scraper can keep a standard HTTP fetch + parse workflow, which makes implementation and scaling much easier.