Logistics data access with Cloudflare and DataDome workflows
Collect vessel schedules, container events, freight rates and port milestones through a consistent access workflow. Cloudflare JS Challenge and Turnstile handling work alongside the DataDome challenge-handling workflow for supported logistics targets. Keep sessions stable and verify container IDs and event timestamps before updating a tracking record or supply-chain dashboard.
Start Free Trial API DOCs Code generator

Why Logistics & Supply Chain Data Scraping Is Hard
Why Is Logistics & Supply Chain Data Collection Always "Unstable"?
Logistics and supply chain data collection is not a one-time crawl - it's a high-frequency, multi-region, multi-platform system that must run continuously in production.
Many logistics platforms, freight forwarder systems, pricing portals, and customs tracking endpoints are protected by Cloudflare and other anti-bot defenses. This often causes scraping jobs to be blocked by verification pages, leading to higher failure rates, delayed delivery, and incomplete datasets.
-
Cloudflare Verification Triggers Too Often
Requests are frequently redirected to challenge pages or CAPTCHAs, replacing real responses and making consistent data extraction and parsing unreliable.
-
Unstable Cross-Region Access and Volatile Latency
International routes can suffer from timeouts and packet loss. Latency spikes reduce crawl success rates and directly impact update frequency and freshness.
-
Sessions and Cookies Are Hard to Maintain
Many sites rely on Cookie/Header/Session validation. Frequent parameter changes can return empty payloads, increasing rule maintenance and engineering costs.
-
Higher Volume Leads to Blocks and Risk Controls
As concurrency increases, rate limits and bans become more aggressive. IPs and sessions get blacklisted, retries keep failing, and costs continue to rise.
Technical Support Contact
Keep verification outside the logistics pipeline
Combine Cloudflare access handling and confirmed DataDome CAPTCHA support with regional requests and response validation. Check shipment identifiers, event times and rate fields so interrupted access does not appear as a delayed container or a changed freight quote.
-
Automatically Handles Cloudflare Challenges
Detects and completes verification flows automatically, avoiding challenge redirects and keeping your requests returning usable data.
-
Smart Session Persistence & Parameter Management
Maintains cookie/header/session consistency to reduce empty responses and repeated verification caused by unstable environments.
-
Global Routing to Reduce Cross-Border Latency
Selects the best route by country/region to significantly reduce timeouts and packet loss, improving stability for international data scraping.
-
Unified Output for Structured Parsing
Normalizes HTML and API responses into consistent outputs - making it easier to extract fields, store data, and integrate with BI or risk-control systems.
Use Cases
Built for logistics & supply chain websites that require bypassing Cloudflare verification to achieve stable, continuous data extraction
Shipment Tracking Data Scraping
Continuously sync pickup, transit, port arrival, customs clearance, delivery, proof of delivery, and exception milestones. Automatically fill tracking gaps to support ETA prediction, delay alerts, and customer status notifications.
Shipping Rate & Quote Data Scraping
Capture air/ocean/rail/truck pricing and track base rates plus surcharges (fuel, peak season, congestion). Enable route comparison and cost modeling to improve quoting accuracy and speed.
Vessel Schedule & Flight Data Scraping
Monitor ETD/ETA, delays, port skips, vessel changes, and lane adjustments. Detect capacity pressure and plan changes early to support allocation decisions and delivery-cycle evaluation.
Customs Status & Compliance Data Scraping
Track declaration progress, inspection status, tax rules, and release milestones. Identify missing documents and compliance risk signals to reduce delays and improve cross-border fulfillment reliability.
Warehouse Fulfillment & Inventory Data Scraping
Aggregate inbound/outbound events, inventory movements, turnover rates, and picking performance. Pinpoint bottlenecks and anomalies to optimize fulfillment, replenishment strategy, and SLA monitoring.
Supply Chain Risk & Incident Monitoring
Monitor delay warnings, abnormal delivery confirmation, returns/refusals, loss/damage, and service-quality trends. Build an auditable incident library to support risk alerts, root-cause attribution, and operational optimization.
Scrapingbypass Onboarding Workflow
1.Create Your Account
Register a Scrapingbypass API account - Sign Up Now
Register a Scrapingbypass Proxy account - Sign Up Now
One account gives you API and proxy access. Log in within 30 days and open Trial Activity from the gift icon to claim trial credits and traffic.
2.Test with the Code Generator
Enter your target URL in the Code Generator to test Cloudflare bypass. For DataDome-protected targets, review the DataDome CAPTCHA solver API workflow and confirm challenge compatibility with support before testing.
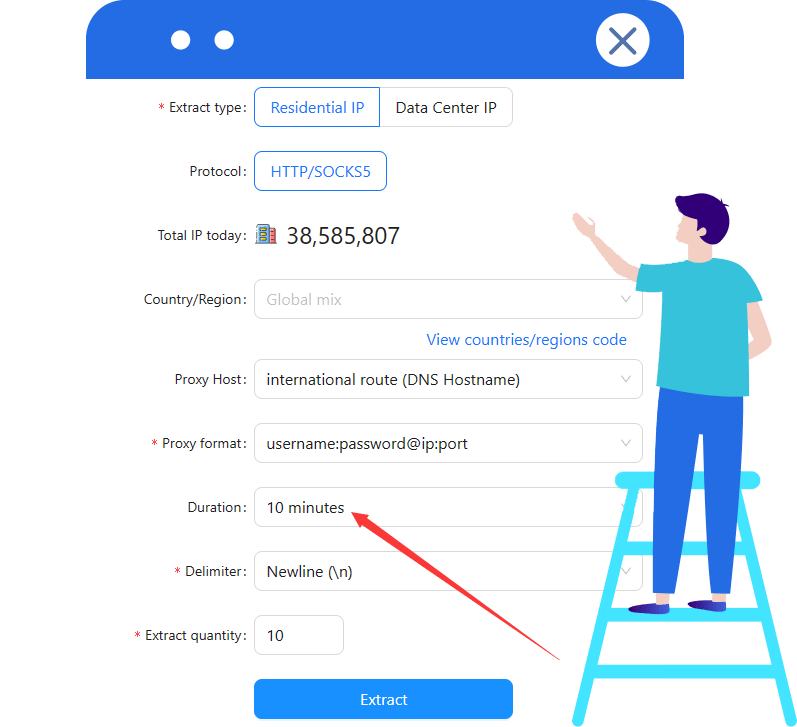
V1 includes a rotating proxy. V2 requires a stable proxy IP; configure a sticky session of at least 10 minutes when using Scrapingbypass rotating proxies.
For assistance, see the API documentation or contact Scrapingbypass Support.
3.Integrate the Scrapingbypass API
Integrate the confirmed Cloudflare or DataDome workflow into your application. Keep the proxy IP and session consistent, then validate the returned content before deployment.
4.Select a Pricing Plan
Choose a plan based on your usage - View Pricing
Choose a credit plan for Cloudflare JS Challenge. For DataDome CAPTCHA handling, confirm compatibility and pricing before purchasing.
For proxy traffic, select a Rotating Datacenter or Rotating Residential proxy plan.
Cloudflare bypass uses API credits and may require proxy support. For DataDome bypass, confirm supported targets and billing before choosing a plan. A proxy alone is not a CAPTCHA solver.
Scrapingbypass API Pricing
Handle Cloudflare challenges on 95%+ of websites and scrape data with confidence
Starting at $0.35 per 1,000 verifications. Failed requests are not charged. Each successful request uses 1 credit (Scrapingbypass V2 uses 3 credits).
Basic Plan
-
$49
-
Credits:80000Validity:30 DaysSpeed:20 req/s
Standard Plan
-
$79
-
Credits:300000Validity:30 DaysSpeed:20 req/s
Advanced Plan
-
$129
-
Credits:1000000Validity:30 DaysSpeed:25 req/s
Pro Plan
-
$259
-
Credits:2200000Validity:30 DaysSpeed:25 req/s
Premium Plan
-
$489
-
Credits:4600000Validity:30 DaysSpeed:30 req/s
-
Best Value
Ultimate Plan
-
$1056
-
Credits:12000000Validity:30 DaysSpeed:30 req/s
Need more credits than the standard plans provide? Get a custom plan tailored to your workload Unlimited credits / Dedicated servers / Higher concurrency / Priority technical support
Contact Us for a Custom Plan Buy Rotating IPsFAQFrequently Asked Questions
Why do logistics and supply chain data scraping projects often trigger Cloudflare verification?
Logistics and supply chain data collection typically involves high request frequency, cross-region traffic, and heavy concurrency. These patterns can easily trigger Cloudflare's security checks, leading to verification pages, challenge flows, or restricted access - resulting in failed crawls and incomplete datasets.
How does Scrapingbypass API prevent scraping failures caused by Cloudflare challenges?
Scrapingbypass API helps handle Cloudflare verification and challenge pages in compliant, authorized scenarios. It stabilizes access so your logistics and supply chain crawlers can consistently retrieve page/API responses, then return HTML/JSON for parsing and storage.
Can Scrapingbypass API deliver structured output for logistics and supply chain data?
Yes. Scrapingbypass API can return raw HTML/JSON, and also support structured delivery based on your project needs - such as tracking events, status updates, timestamps, locations, carriers, channels, and fees - so you can directly feed databases, BI dashboards, or supply chain monitoring systems.
Is Scrapingbypass API a good fit for long-running, high-volume supply chain scraping workloads?
Absolutely. Logistics and supply chain collection is often a long-term operation. Scrapingbypass API supports session persistence, smart routing, retry strategies, and stable access mechanisms - helping reduce failure spikes and enabling enterprise-scale delivery.
Does Scrapingbypass API support cross-border logistics data collection?
Yes. Cross-border logistics and supply chain tracking requires reliable global access. Scrapingbypass API supports multi-region endpoints and intelligent routing strategies to improve success rates and freshness - ideal for international tracking, rate monitoring, and customs clearance status updates.
Is it compliant to use Scrapingbypass API for logistics and supply chain data scraping?
Cloudbypass recommends using the API only within legal and authorized boundaries - such as your own sites, partner-authorized endpoints, or publicly available data sources. We also support audit logs and usage analytics to help teams manage compliance and delivery tracking.