Risk intelligence access with Cloudflare and DataDome verification handling
Collect permitted public risk indicators, domain evidence and landing-page snapshots through a traceable access workflow. Cloudflare challenge handling and DataDome verification diagnostics help separate blocked access from meaningful source evidence. Retain request context and validate page content before feeding risk scores or alerts; failed verification alone is not evidence of a threat.
Start Free Trial API DOCs Code generator
Why It's Hard to Collect Security Risk Intelligence
Common Obstacles in Security Risk Intelligence Data Collection
Risk intelligence websites are heavily protected, updated frequently, and often change their page structures. Traditional scraping workflows face constant challenge pages, unstable success rates, and incomplete datasets - making it difficult to support real-time monitoring and rapid strategy iteration.
-
Frequent Cloudflare Verification & Challenge Blocks
Requests are forced into verification pages or redirects, preventing data ingestion and causing large-scale task failures.
-
Lower Success Rates Under High Concurrency
As concurrency increases, anti-bot limits trigger quickly - responses slow down, throttling kicks in, or connections get blocked entirely.
-
Fast-Changing Page Structures & Fields
Layouts and data fields shift often, breaking parsing rules and disrupting data continuity over time.
-
Missing and Duplicate Risk Data
Unstable pipelines cause data gaps, while duplicate collection increases cost and reduces analysis quality.
Technical Support Contact
Scrapingbypass API: More Reliable Risk Intelligence Data Collection
Keep Cloudflare checks and supported DataDome CAPTCHA handling in the access layer. Preserve status, content type and source timestamps so verification failures can be diagnosed without contaminating threat evidence.
-
Bypass Cloudflare Challenges to Access Real Content
Automatically handles Cloudflare challenges and blocking logic to improve accessibility, ensuring your scraping tasks consistently return valid, usable pages.
-
High-Concurrency, Cross-Platform Data Collection
Supports multi-threaded and distributed job execution while staying stable under heavy concurrency, reducing batch failures, timeouts, and retry overhead.
-
Structured HTML/JSON Output for Faster Parsing
Returns ready-to-parse HTML/JSON so you can extract, normalize, and store data with less engineering effort - cutting ongoing maintenance and adaptation costs.
-
Lower Bandwidth, Higher Throughput
Optimized request workflows reduce unnecessary resource loading, helping you lower traffic costs while increasing overall scraping throughput and efficiency.
Use Cases
Built for Risk Intelligence Scraping That Must Bypass Cloudflare and Other Verification Systems for Stable Web Data Collection
Risky IP Reputation Intelligence Scraping
Continuously monitor proxy abuse, anomalous access, and risk score changes. Enrich IP reputation profiles to support blocking strategies, threshold tuning, and access control decisions - improving blacklist hit rates and detection accuracy.
Malicious Domain & Phishing Site Collection
Reliably capture key page content and link-chain intelligence from phishing pages, spoofed sites, and malicious redirect landing pages - supporting fraud pattern detection and security operations evidence trails.
Underground Site & Attack Surface Monitoring
Schedule scraping and change detection on heavily protected sources to track underground resources, script payload drops, and abnormal page updates - spotting new attack entry points faster and accelerating incident response.
Account Anomaly Signal Collection
Collect signals tied to suspicious logins, mass registrations, and credential stuffing attempts. Combine risk features with device fingerprinting and access pattern analysis to improve model training, reduce false positives, and strengthen account protection.
Fraud Ad & Landing Page Scraping
Track fraudulent ad landing pages and redirect flows used by black/gray-hat campaigns. Capture structure, key elements, and content changes continuously to identify template evolution and generate durable blocking signals.
Threat Intelligence Aggregation & Continuous Updates
Ingest and unify risk intelligence from multiple sources into a searchable dataset with timeline updates. Enable alert correlation, risk score refresh, and cross-source validation - boosting end-to-end fraud prevention and security decision-making.
Scrapingbypass Onboarding Workflow
1.Create Your Account
Register a Scrapingbypass API account - Sign Up Now
Register a Scrapingbypass Proxy account - Sign Up Now
One account gives you API and proxy access. Log in within 30 days and open Trial Activity from the gift icon to claim trial credits and traffic.
2.Test with the Code Generator
Use the Code Generator to configure and test Cloudflare or DataDome requests. Both use the same integration logic and request code. Keep the proxy IP, cookies and session consistent.
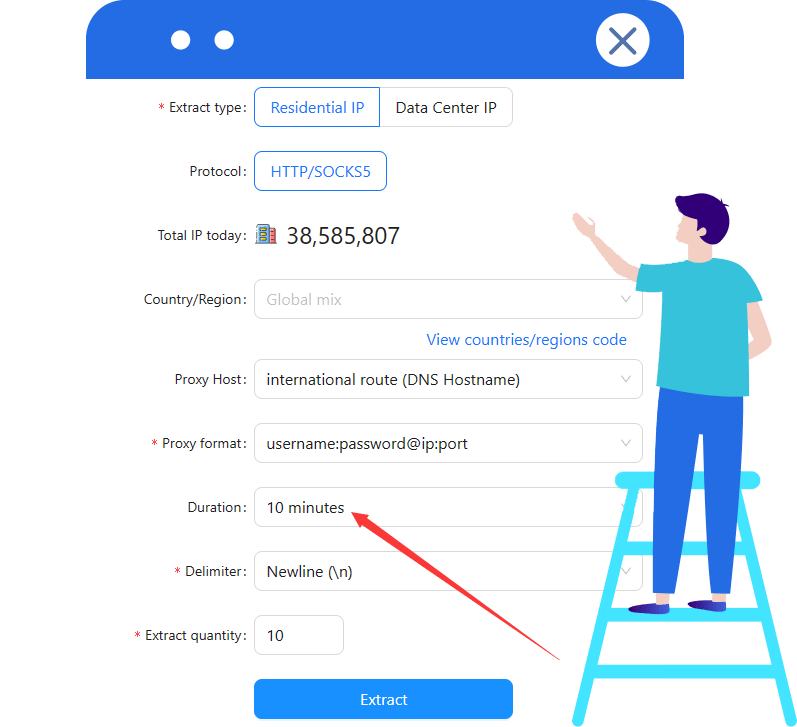
V1 includes a rotating proxy. V2(s) requires a stable proxy IP; configure a sticky session of at least 10 minutes when using Scrapingbypass rotating proxies.
For assistance, see the API documentation or contact Scrapingbypass Support.
3.Integrate the Scrapingbypass API
Integrate your tested request code into the application. Cloudflare and DataDome share the same API integration and call pattern. Validate response status and content before parsing, pagination or automation.
4.Select a Pricing Plan
After testing, choose a plan based on your usage. Cloudflare and DataDome share the same API credits, consumption rules and pricing. View Pricing
For proxy traffic, select a Rotating Datacenter or Rotating Residential proxy plan.
Cloudflare and DataDome challenge handling consume API credits; some workflows also need a proxy. API credits and proxy traffic are billed separately. A proxy connection does not replace CAPTCHA handling.

Scrapingbypass API Pricing
Test target compatibility, then choose an API plan for your workload
Each successful request costs 1 credit. Successful V2(s) verification costs 2 extra credits, not refunded if the later response fails. Proxy traffic is billed separately.
Basic Plan
-
$49
-
Credits:80000Validity:30 DaysSpeed:20 req/s
Standard Plan
-
$79
-
Credits:300000Validity:30 DaysSpeed:20 req/s
Advanced Plan
-
$129
-
Credits:1000000Validity:30 DaysSpeed:25 req/s
Pro Plan
-
$259
-
Credits:2200000Validity:30 DaysSpeed:25 req/s
Premium Plan
-
$489
-
Credits:4600000Validity:30 DaysSpeed:30 req/s
-
Best Value
Ultimate Plan
-
$1056
-
Credits:12000000Validity:30 DaysSpeed:30 req/s
Need more credits than the standard plans provide? Get a custom plan tailored to your workload Unlimited credits / Dedicated servers / Higher concurrency / Priority technical support
Contact Us for a Custom Plan Buy Rotating IPsFAQFrequently Asked Questions
How can Scrapingbypass API be used for security & risk intelligence data collection?
You can use the target intelligence site URL as the entry point and fetch parse-ready page content via Scrapingbypass API. Then, extract risk IPs, domains, page fingerprints, and related signals based on your own rules to build a stable, automated intelligence pipeline.
How does Scrapingbypass API bypass Cloudflare checks to retrieve page data?
Scrapingbypass API is optimized for Cloudflare verification and challenge pages, reducing the impact of blocks on your data pipeline. It returns real page content more consistently, improving success rate and coverage across large-scale scraping tasks.
Why do security & risk intelligence collection tasks fail more often under high concurrency?
Risk-focused sites are highly sensitive to request frequency and behavior patterns. High concurrency can quickly trigger challenges, rate limits, or bans. Scrapingbypass API provides a more reliable access workflow to reduce failures - ideal for bulk collection and continuous monitoring.
Does Scrapingbypass API return HTML or JSON, and how does that help parsing?
Scrapingbypass API supports both HTML and JSON output, so you can choose the best format for your data structure. Structured responses reduce maintenance when pages change, making extraction, cleaning, and storage much faster and more reliable.
How do you avoid missing data and duplicate entries in security intelligence collection?
We recommend using an "incremental updates + deduplication + timeline comparison" workflow. With Scrapingbypass API delivering stable access, you reduce missed data caused by challenge blocks and keep your dataset continuous and accurate.
How can you maintain long-term stability when collecting data from Cloudflare-protected intelligence sites?
The key is a consistently high success rate and a continuously available access pipeline. Scrapingbypass API is purpose-built for Cloudflare verification flows, making it a strong fit for long-term monitoring and always-on intelligence collection.