
Why Scrapingbypass
Regional SERP monitoring with a web scraping API
Compare rankings, local SERP layouts, competitor visibility and ad landing pages across regions. Scrapingbypass provides HTML snapshots, screenshots and access logs for search monitoring. When a landing page returns Cloudflare or DataDome verification, apply response validation before recording a result so a CAPTCHA screen does not become a ranking or campaign signal.
Keep evidence for audits
Capture HTML and screenshots together with status logs, making it easier to explain regional ranking changes and verify whether search experiences differ by market.
Why Scrapingbypass
Regional SERP monitoring with a web scraping API
Use a web scraping API for regional SERP monitoring, ad checks and competitor research. For Google search results, preserve country, language and session settings and retain HTML snapshots and screenshots as ranking evidence.
Access success stability 95%
Access-layer maintenance saved 80%
Geo SERP results
Fetch search results by country, language, device and proxy location.
Ranking monitor
Track rankings for your brand, target keywords and competitors.
Ad checks
Verify ad display, redirects, and landing pages.
HTML evidence
Keep HTML, screenshots, and access timestamps.
API / Proxy / Browser
Manage regional access, sessions and screenshots in one layer
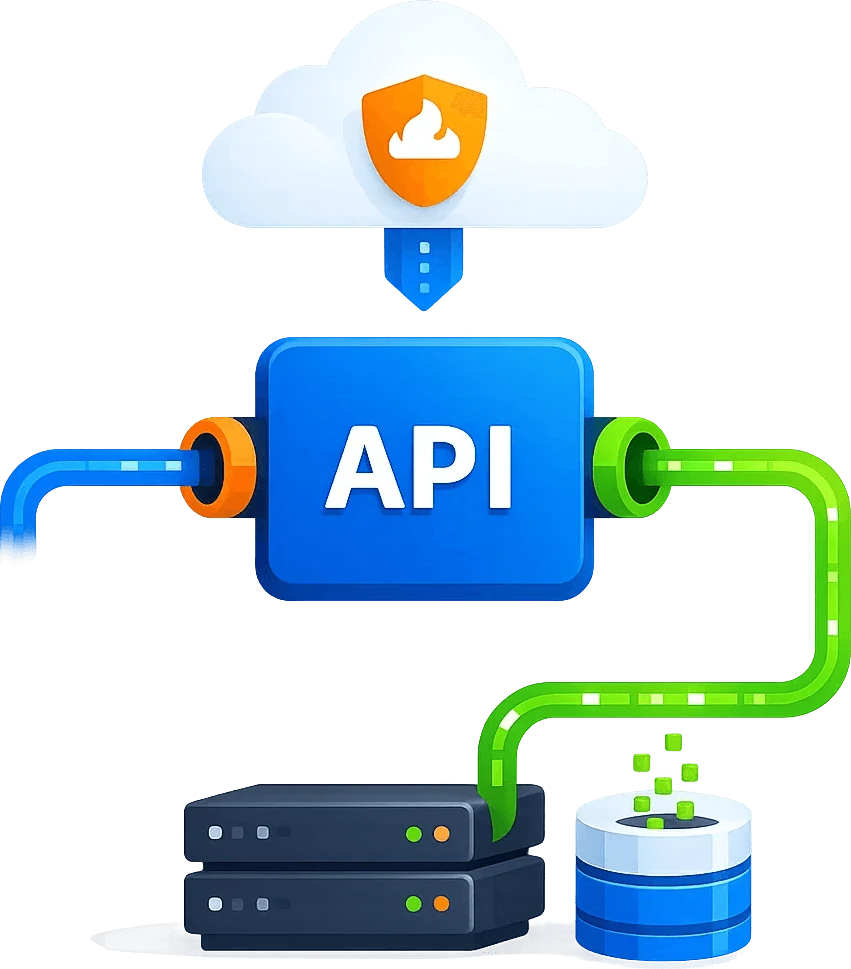
Move challenge handling, dynamic pages, proxy exits, retry logic, and logs out of business scripts and into a reusable web access layer.
STEP 01
Geo SERP results
Fetch search results by country, language, device and proxy location.
STEP 02
Ranking monitor
Track rankings for your brand, target keywords and competitors.
STEP 03
Ad checks
Verify ad display, redirects, and landing pages.
STEP 04
HTML evidence
Keep HTML, screenshots, and access timestamps.
Use cases
Representative business scenarios
From one-off validation to long-running monitoring, combine capabilities by page complexity and output requirements.
Existing crawler integration
Keep current collection logic and move access stability into the Scrapingbypass layer.
Browser automation
Add proxy, session, screenshot, and retry capabilities to Playwright, Selenium, and Puppeteer.
Geo access verification
Validate pages, ads, search results, and redirects by country and language.
Long-term monitoring
Track availability with logs, screenshots, status codes, and retry rules.
Budget estimation
Estimate launch cost by requests, traffic, screenshots, rendering, and retries.
Integration steps
Connect the Scrapingbypass access layer in 4 steps
Validate one high-value page first, then expand into scheduled workflows, batch collection, or monitoring systems.
01. Define target access
Confirm URLs, regions, frequency, output format, and workflow scope.
02. Choose access strategy
Pick API, rendering, screenshots, dynamic IPs, sticky sessions, and retry rules.
03. Connect business systems
Send results to crawlers, AI agents, workflows, QA, or internal monitoring.
04. Review logs and optimize
Use status codes, failure reasons, screenshots, and logs to improve stability.
FAQ
Frequently asked questions
How is it different from a normal proxy?
A normal proxy mainly provides an exit. Scrapingbypass also covers challenge handling, geo context, dynamic pages, screenshots, structured output, retries, and logs.
Can existing crawlers use it?
Yes. Existing crawlers can connect through Proxy mode, while complex pages can be handled through API mode.
Does it support geo exits?
Yes. Tasks can be organized by country, language, device, and exit region for SEO, ads verification, and geo monitoring.