Public social-content access with Cloudflare and DataDome workflows
Build permitted public-content aggregation and social-listening pipelines around validated pages. Scrapingbypass handles Cloudflare verification; DataDome CAPTCHA loop troubleshooting helps plan supported DataDome workflows with consistent sessions and bounded retries. Check post identity and expected content before recording deletions or trends, and respect login and access restrictions.
Start Free Trial API DOCs Code generator

Why Social Media Data Extraction Is So Challenging
Why Is Social Media Content Data Scraping So Unstable?
Most social platforms run aggressive Cloudflare security policies and behavioral risk controls. It's common to encounter verification redirects, JS challenge blocks, request failures, frequent bans, and rate limits - leading to broken scraping workflows, missing data, and rapidly rising infrastructure costs.
-
Cloudflare Blocks Trigger Too Often
Cloudflare's 5-second challenge and JS verification can pop up unexpectedly, breaking sessions and causing repeated retry loops.
-
Accounts and IPs Get Flagged Easily
High-concurrency scraping often triggers throttling and bans, causing account instability and visible gaps in data continuity.
-
Dynamic Rendering Is Hard to Reproduce
Many pages rely on JavaScript rendering and API-driven content loading, which can result in empty responses, layout shifts, or inconsistent fields.
-
Data Quality Is Difficult to Standardize
The same task may have multiple entry points and layouts, making field mapping inconsistent and downstream cleaning/merging much harder.
Technical Support Contact
Streamline Social Media Content Data Collection with Scrapingbypass API
Handle Cloudflare challenges and confirmed DataDome verification flows before parsing public posts. Return a diagnostic when access fails rather than treating a CAPTCHA screen as missing content or repeatedly retrying a denied request.
-
Automatically Handle Cloudflare Challenges
Detect and complete Cloudflare verification flows automatically to avoid challenge pages and empty responses - keeping your data scraping pipeline consistently reliable.
-
Keep Sessions and Request Parameters Consistent
Maintain Cookies, Headers, and Sessions automatically to reduce request volatility, prevent unexpected redirects, and minimize re-verification issues.
-
Global Routing to Reduce Cross-Border Latency
Route requests through optimized regional paths by country and location to reduce timeouts and packet loss - improving speed and stability for cross-region scraping.
-
Unified Output for Easy Structured Parsing
Normalize HTML and API responses into clean, process-ready results - making it easier to extract fields, store data, and integrate with BI dashboards or risk control systems.

Use Cases
Built for Social Media Content Scraping Scenarios That Require Cloudflare Bypass and Stable Data Extraction at Scale
Trending Feed Tracking and Aggregation
Continuously scrape homepages and recommendation feeds to consolidate trending posts and signals. Supports high-frequency updates and incremental sync - ideal for content performance dashboards, trend monitoring, and topic discovery systems.
Hashtag and Trend Analysis
Build continuous data collection around hashtag and topic pages to capture momentum changes and content diffusion paths. Perfect for trend forecasting, content strategy evaluation, and attribution analysis on campaign performance.
Account Monitoring and Competitor Tracking
Scrape profile pages and new posts to track publishing frequency, engagement performance, and content structure shifts. Great for competitor benchmarking, account portfolio management, and pre-launch ad validation.
Comment Threads and Interaction Insights
Capture comment threads, likes, and reply relationships to build engagement graphs and sentiment analysis pipelines. Useful for public opinion alerts, brand reputation insights, and customer support risk detection.
Creative Asset Archiving and Content Library
Continuously archive viral content into a searchable asset library. Organize by topic, tags, and publish time - ideal for ad creative breakdowns and repeatable content iteration.
Consistent Multi-Region and Multi-Site Scraping
Handle region-specific page structures and access rules with a unified scraping endpoint and consistent response format. Ideal for global data platforms, multilingual content monitoring, and international operations.
Scrapingbypass Onboarding Workflow
1.Create Your Account
Register a Scrapingbypass API account - Sign Up Now
Register a Scrapingbypass Proxy account - Sign Up Now
One account gives you API and proxy access. Log in within 30 days and open Trial Activity from the gift icon to claim trial credits and traffic.
2.Test with the Code Generator
Use the Code Generator to configure and test Cloudflare or DataDome requests. Both use the same integration logic and request code. Keep the proxy IP, cookies and session consistent.
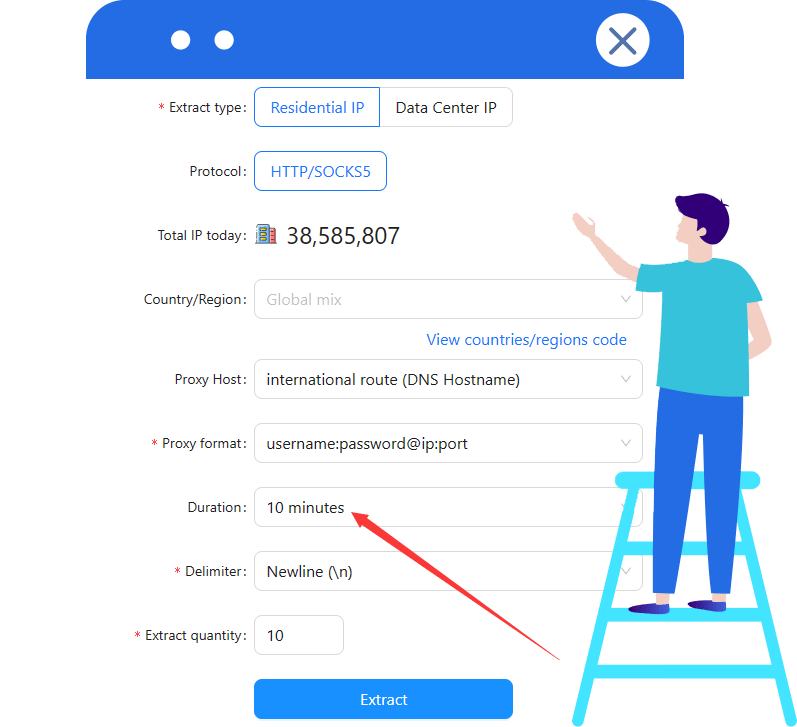
V1 includes a rotating proxy. V2(s) requires a stable proxy IP; configure a sticky session of at least 10 minutes when using Scrapingbypass rotating proxies.
For assistance, see the API documentation or contact Scrapingbypass Support.
3.Integrate the Scrapingbypass API
Integrate your tested request code into the application. Cloudflare and DataDome share the same API integration and call pattern. Validate response status and content before parsing, pagination or automation.
4.Select a Pricing Plan
After testing, choose a plan based on your usage. Cloudflare and DataDome share the same API credits, consumption rules and pricing. View Pricing
For proxy traffic, select a Rotating Datacenter or Rotating Residential proxy plan.
Cloudflare and DataDome challenge handling consume API credits; some workflows also need a proxy. API credits and proxy traffic are billed separately. A proxy connection does not replace CAPTCHA handling.

Scrapingbypass API Pricing
Test target compatibility, then choose an API plan for your workload
Each successful request costs 1 credit. Successful V2(s) verification costs 2 extra credits, not refunded if the later response fails. Proxy traffic is billed separately.
Basic Plan
-
$49
-
Credits:80000Validity:30 DaysSpeed:20 req/s
Standard Plan
-
$79
-
Credits:300000Validity:30 DaysSpeed:20 req/s
Advanced Plan
-
$129
-
Credits:1000000Validity:30 DaysSpeed:25 req/s
Pro Plan
-
$259
-
Credits:2200000Validity:30 DaysSpeed:25 req/s
Premium Plan
-
$489
-
Credits:4600000Validity:30 DaysSpeed:30 req/s
-
Best Value
Ultimate Plan
-
$1056
-
Credits:12000000Validity:30 DaysSpeed:30 req/s
Need more credits than the standard plans provide? Get a custom plan tailored to your workload Unlimited credits / Dedicated servers / Higher concurrency / Priority technical support
Contact Us for a Custom Plan Buy Rotating IPsFAQFrequently Asked Questions
Why do social media scraping tasks get hit by Cloudflare's 5-second check?
Many social platforms use Cloudflare for protection. When it detects high-frequency traffic or suspicious behavior patterns, it may trigger the 5-second check (JS Challenge) to block automated requests. Scrapingbypass API can automatically handle these verification steps to significantly improve your success rate.
What types of Cloudflare verification can Scrapingbypass API handle?
Scrapingbypass API handles common Cloudflare JavaScript Challenges (the 5-second check) and supports human verification mechanisms like Turnstile - making it a solid fit for a wide range of social media data extraction use cases.
Can proxies alone solve Cloudflare blocks?
Not reliably. Proxies help distribute traffic and reduce the chance of bans, but Cloudflare often layers in JS execution, challenge pages, and behavioral detection. Simply rotating IPs doesn't guarantee consistent access. Scrapingbypass API embeds verification handling directly into the request flow, so your pipeline stays stable.
For social media extraction, should I use HTML output or JSON?
If you need full page structure for secondary parsing, HTML is more flexible. If you want data that can be stored and analyzed immediately, JSON/structured output is more efficient. Scrapingbypass API supports both HTML and JSON responses, making it easy to plug into different data pipelines.
Does high concurrency increase verification triggers or blocking risks?
Yes. The higher the concurrency, the more likely you are to trigger anti-abuse systems. We recommend splitting workloads, controlling request rates, and managing sessions properly. Scrapingbypass API is optimized for high-concurrency stability and can greatly reduce retry costs caused by failed requests.
Is it hard to integrate Scrapingbypass API for social media scraping?
Not at all. Just provide the target URL and your API key to start calling it - works with Python, Node.js, and more. You can also use the code generator to quickly test whether a site is accessible before rolling it into production.