
Why Scrapingbypass
Track public Web3 pages that are not available from on-chain data alone
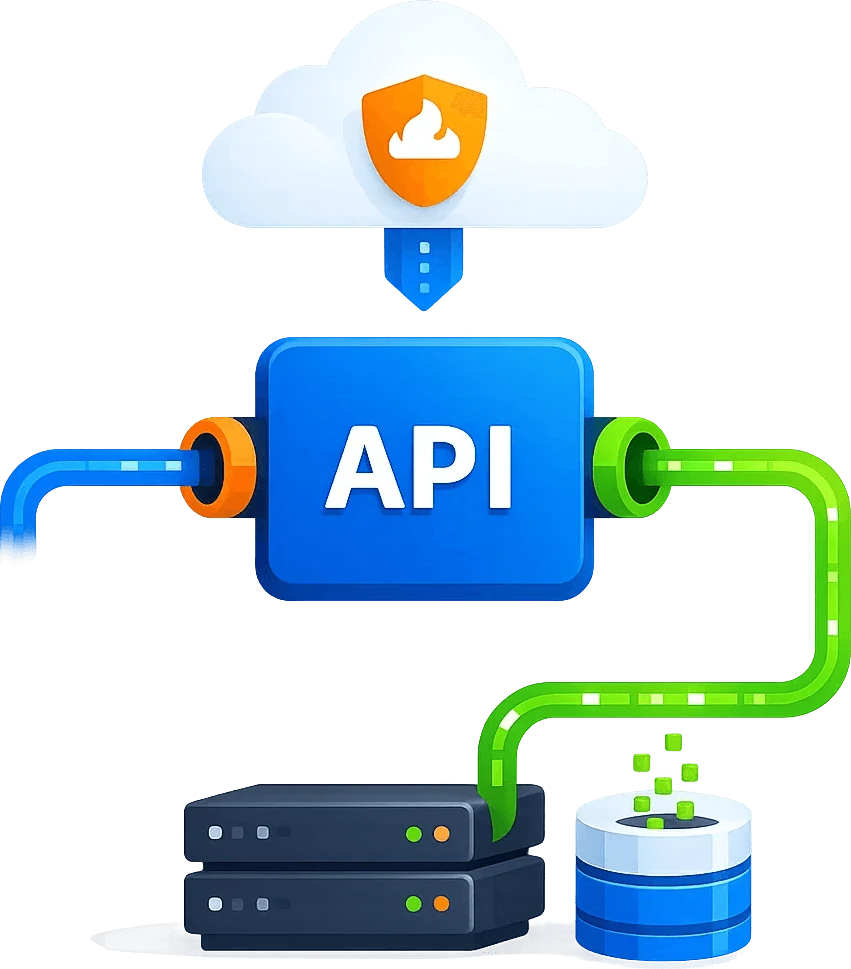
Bring permitted exchange announcements, ETF pages, token listings, project documentation and crypto news into one off-chain monitoring pipeline. Scrapingbypass combines regional access, screenshots, Markdown, JSON and logs with Cloudflare handling. For DataDome-protected sources, confirm supported CAPTCHA handling and validate announcement text and timestamps before producing a market update.
Keep monitoring auditable
Use screenshots, status codes, timestamps and structured outputs to support alerts, dashboards and AI summaries for crypto market intelligence.
Solution 2: proxy and session strategy
Choose dynamic residential IP, dynamic datacenter IP, rotation or sticky sessions by task type for long-term monitoring, multi-region verification and project isolation.
Cloudflare challenge handling
Track public Web3 pages that are not available from on-chain data alone
Web3 data teams often need off-chain signals such as exchange announcements, ETF pages, token listings, project documentation, crypto news and social trend pages. Scrapingbypass provides web access, screenshots, Markdown, JSON and logs for these monitoring workflows.
Challenge pass stability 95%
Access-layer maintenance reduction 80%
Challenge handling
Keep Cloudflare handling and supported DataDome workflows in one access layer, with clear failure diagnostics.
IP rotation and sessions
Use rotating residential or datacenter IPs, sticky sessions and bounded retries for ongoing monitoring.
Regional access
Choose proxy locations by country, city and task.
Status logs and compliance
Keep status codes, screenshots and failure details for auditing.
Cloudflare / Turnstile / WAF
Bring exchange announcements, ETF pages and project updates into stable monitoring
Bring permitted off-chain pages into Web3 research with Cloudflare handling or a supported DataDome workflow, then validate announcement content and timestamps.
STEP 01
Market pages
Monitor exchanges, ETF pages, DID/NFT markets and crypto market pages.
STEP 02
Announcements and news
Collect project announcements, news, blogs and campaign pages while reducing 403 and geo failures.
STEP 03
Project ecosystem
Combine official sites, social pages, KOL pages and ecosystem data for a fuller view.
STEP 04
Research input
Turn web results into structured data for dashboards, agents and reports.
Use Cases
Typical applications for Web3 Crypto Data Monitoring
For Web3 data platforms, crypto research, exchange service providers, AI agents and market data teams, covering business scenarios from one-off access to long-term monitoring.
Exchange announcement monitoring
Build stable access, geo verification, screenshot evidence and structured results around Exchange announcement monitoring, reducing manual checks and duplicate script maintenance.
ETF and market pages
Build stable access, geo verification, screenshot evidence and structured results around ETF and market pages, reducing manual checks and duplicate script maintenance.
Project website updates
Build stable access, geo verification, screenshot evidence and structured results around Project website updates, reducing manual checks and duplicate script maintenance.
DID/NFT market data
Build stable access, geo verification, screenshot evidence and structured results around DID/NFT market data, reducing manual checks and duplicate script maintenance.
AI crypto research assistants
Build stable access, geo verification, screenshot evidence and structured results around AI crypto research assistants, reducing manual checks and duplicate script maintenance.
Implementation steps
Connect the Scrapingbypass access layer in 4 steps
Start with one high-value page or task, validate access, then expand into scheduled workflows.
01. Define the access target
Confirm URL, region, frequency, output format and business boundary.
02. Choose an access strategy
Select API, rendering, screenshots, dynamic IP, sticky session or retry strategy.
03. Connect business systems
Send results to crawlers, AI agents, workflows, QA or internal monitoring systems.
04. Review and optimize
Track status codes, failure reasons, screenshots and logs to keep access stable.
FAQ
Common questions
How is this different from a normal proxy?
A normal proxy mainly provides an exit. Scrapingbypass focuses on the full access workflow: regional environment, dynamic pages, challenge handling, screenshots, structured output, retries and logs.
Is it suitable for non-developers and AI coding users?
Yes. Teams can build the business logic with templates, workflow tools or AI-generated code, then hand protected web access to the Scrapingbypass API.
How should compliance risk be controlled?
Use it for public data, authorized data and legitimate business workflows. Add domain allowlists, rate limits, task logs and human review where needed.