Travel-data access across Cloudflare and DataDome verification
Monitor permitted fares, hotel availability, ticket listings and visa updates with regional settings preserved. Cloudflare handling and the DataDome solver API workflow help plan verification for supported travel targets. Keep the approved session consistent and check travel dates, currency and availability before comparing prices or updating your monitoring results.
Start Free Trial API DOCs Code generator

Why Travel, Visa & Ticketing Data Scraping Is Hard
Four Stability Challenges in Travel, Visa & Ticketing Data Scraping
From deal monitoring to itinerary planning, real-time accuracy and completeness are critical for travel data workflows. But in real-world scraping, verification systems, dynamic content, and rapid price changes significantly increase cost and failure rates.
-
Cloudflare verification frequently blocks requests
Challenge pages interrupt your scraping flow, causing parsing failures and missing data across key pages.
-
Prices and availability change too fast to track
Fares and room inventory update constantly - delayed scraping means you miss low-price windows and important shifts.
-
Dynamic rendering hides critical content
With heavy asynchronous loading, direct HTTP requests may not return full content, making field extraction unstable and prone to drift.
-
High-concurrency scraping triggers anti-bot blocks
As concurrency and frequency increase, rate limits and bans kick in - IPs and sessions fail, and long-running jobs can't stay stable.
Technical Support Contact
Scrapingbypass API Core Capabilities: More Reliable Travel, Visa & Ticketing Data Collection
Pair Cloudflare challenge handling with a confirmed DataDome integration before parsing fare or availability pages. Preserve the region and session, then verify dates, currency and inventory so a challenge response cannot become a booking result.
-
Stable Access with Cloudflare Bypass
Automatically handles Cloudflare challenges to increase request pass rates, reduce blocks, and minimize costly data gaps or re-crawling operations.
-
High-Concurrency Crawling & Task Scheduling
Supports multi-threaded and parallel scraping workflows with smart rate control for consistent throughput - perfect for fare monitoring, bulk extraction, and real-time travel price intelligence.
-
Lower Ban Risk and Failure Rates
Improves reliability with a more stable request pipeline and retry strategies, reducing common 429/403 failures and keeping long-running crawlers continuously operational.
-
Structured Web Page Output for Parsing
Fetch full page results for easier parsing and field extraction (flights, hotels, visa rules, and more), while minimizing inconsistencies caused by rendering differences.

Use Cases
Built for travel, visa, and ticketing websites that require Cloudflare bypass to enable stable, high-success-rate data collection
Flight Search & Calendar Fare Monitoring
Collect flight search results, calendar lowest fares, and seat availability changes. Continuously monitor routes and dates to power deal alerts, fare comparison tools, and pricing prediction models with reliable data feeds.
Hotel Rates, Availability & Cancellation Policy Collection
Extract room types, availability status, price fluctuations, and cancellation rules. Ideal for multi-channel price comparison, inventory monitoring, and package strategy analysis to improve booking conversion and margin control.
Attraction Ticket Inventory & Reservation Rule Scraping
Capture ticket prices, opening hours, reservation limits, and capacity control policies to build ticket aggregators and inventory alerts - supporting itinerary recommendations and peak-season resource planning.
Visa Requirements & Policy Update Monitoring
Track visa types, document checklists, fees, processing times, and policy changes. Keep visa services and travel platforms accurate and up to date while reducing manual maintenance and customer support workload.
Structured Extraction for Refund, Change & Baggage Rules
Continuously collect and compare refund/change terms, baggage allowances, and add-on fees. Generate clearer rule summaries to reduce decision friction and lower after-sales disputes.
Cross-Platform Price Aggregation & Data Normalization
Align pricing, inventory, and policy fields across multiple platforms to solve inconsistent schemas and delayed updates, building a unified data foundation for metasearch engines, channel monitoring, and travel supply analytics.
Scrapingbypass Onboarding Workflow
1.Create Your Account
Register a Scrapingbypass API account - Sign Up Now
Register a Scrapingbypass Proxy account - Sign Up Now
One account gives you API and proxy access. Log in within 30 days and open Trial Activity from the gift icon to claim trial credits and traffic.
2.Test with the Code Generator
Use the Code Generator to configure and test Cloudflare or DataDome requests. Both use the same integration logic and request code. Keep the proxy IP, cookies and session consistent.
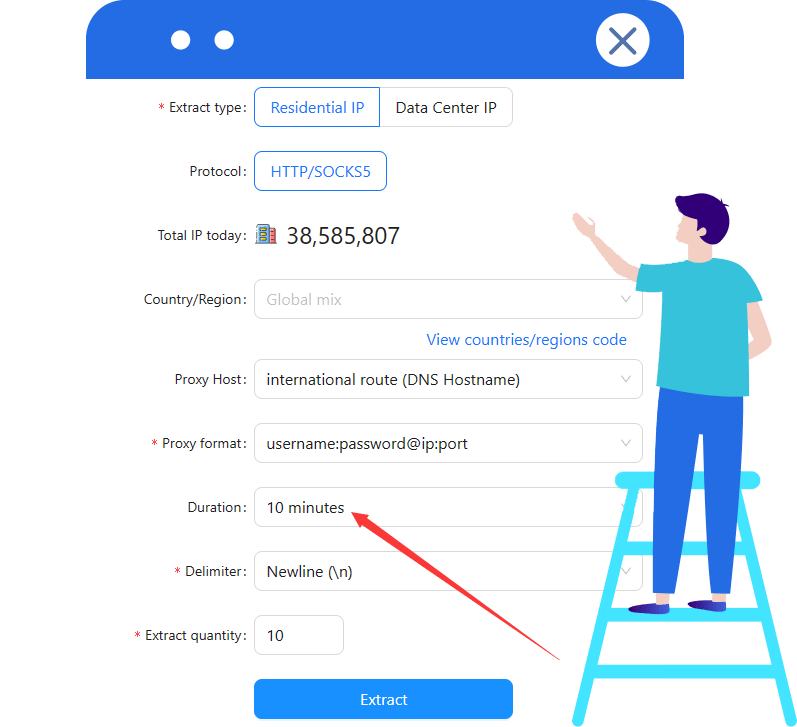
V1 includes a rotating proxy. V2(s) requires a stable proxy IP; configure a sticky session of at least 10 minutes when using Scrapingbypass rotating proxies.
For assistance, see the API documentation or contact Scrapingbypass Support.
3.Integrate the Scrapingbypass API
Integrate your tested request code into the application. Cloudflare and DataDome share the same API integration and call pattern. Validate response status and content before parsing, pagination or automation.
4.Select a Pricing Plan
After testing, choose a plan based on your usage. Cloudflare and DataDome share the same API credits, consumption rules and pricing. View Pricing
For proxy traffic, select a Rotating Datacenter or Rotating Residential proxy plan.
Cloudflare and DataDome challenge handling consume API credits; some workflows also need a proxy. API credits and proxy traffic are billed separately. A proxy connection does not replace CAPTCHA handling.

Scrapingbypass API Pricing
Test target compatibility, then choose an API plan for your workload
Each successful request costs 1 credit. Successful V2(s) verification costs 2 extra credits, not refunded if the later response fails. Proxy traffic is billed separately.
Basic Plan
-
$49
-
Credits:80000Validity:30 DaysSpeed:20 req/s
Standard Plan
-
$79
-
Credits:300000Validity:30 DaysSpeed:20 req/s
Advanced Plan
-
$129
-
Credits:1000000Validity:30 DaysSpeed:25 req/s
Pro Plan
-
$259
-
Credits:2200000Validity:30 DaysSpeed:25 req/s
Premium Plan
-
$489
-
Credits:4600000Validity:30 DaysSpeed:30 req/s
-
Best Value
Ultimate Plan
-
$1056
-
Credits:12000000Validity:30 DaysSpeed:30 req/s
Need more credits than the standard plans provide? Get a custom plan tailored to your workload Unlimited credits / Dedicated servers / Higher concurrency / Priority technical support
Contact Us for a Custom Plan Buy Rotating IPsFAQFrequently Asked Questions
Why do travel, visa, and ticketing data scrapers often trigger Cloudflare challenges?
Travel websites usually run strict anti-bot and risk-control systems. High-frequency visits, abnormal behavior patterns, and automated requests can easily trigger Cloudflare challenges. Scrapingbypass API helps bypass Cloudflare verification, reducing blocks, inaccessible pages, and scraping failures.
How does Scrapingbypass API improve the success rate of travel, visa, and ticketing data collection?
By bypassing Cloudflare challenges and improving request stability, Scrapingbypass API makes it easier to retrieve complete page content reliably. Combined with concurrency control and retry strategies, it can significantly reduce 403/429 failures and keep jobs running continuously.
What should I do if data on search pages and detail pages doesn't match?
Travel pages often use dynamic rendering and layered loading, which can cause different entry points to show different results. We recommend using Scrapingbypass API to reliably access key pages, and splitting your pipeline into "List Discovery -> Detail Enrichment -> Rule Validation" to improve structured consistency.
How can I track price fluctuations and perform incremental updates for travel, visa, and ticketing data?
Build incremental jobs indexed by "route/date/room type/visa type" run them on a minute-level or hourly schedule, and store key price points and rule versions for each run. Scrapingbypass API helps prevent gaps caused by verification blocks, keeping monitoring continuous and reliable.
Why is it easier to get blocked at high concurrency - and can Scrapingbypass API help?
High concurrency amplifies abnormal traffic patterns and request frequency, which can trigger platform risk controls. Scrapingbypass API supports more reliable request pass-through and retry strategies. With sensible concurrency and pacing, you can strike a better balance between throughput and stability.
Does bypassing Cloudflare with Scrapingbypass API affect parsing or data structure?
No. Scrapingbypass API is designed to ensure stable access and retrievable results. The page content you collect can still be parsed with your existing rules to extract fields like flights, hotels, tickets, and visa policies - making it easy for downstream cleaning, alignment, storage, and analytics.