Media-metadata access with Cloudflare and DataDome workflows
Collect permitted listing pages, asset details and licensed metadata through a reusable access pipeline. Scrapingbypass handles Cloudflare verification, while the DataDome puzzle CAPTCHA workflow guides supported DataDome targets. Validate asset IDs and metadata before indexing; verification handling does not grant download rights or override content restrictions.
Start Free Trial API DOCs Code generator
Why Video & Image Asset Data Scraping Is So Challenging
Why is video and image asset scraping so hard to keep stable?
Most media platforms rely on dynamic rendering and aggressive anti-scraping protections. Traditional crawlers often get blocked by verification challenges, causing high failure rates, delayed updates, and steadily rising operational costs.
-
Cloudflare verification frequently blocks scraping requests
Once a request triggers a challenge page, the response becomes invalid - breaking your entire scraping workflow.
-
Dynamic rendering makes it difficult to capture the real page content
Listing pages and detail pages load asynchronously, so raw HTML is incomplete and parsing results miss critical fields.
-
High-concurrency scraping is more likely to trigger bans and rate limits
As traffic scales up, platforms detect automation faster - 429/403 errors spike and batch jobs fail.
-
Frequent layout changes dramatically increase maintenance overhead
Selectors and fields shift often, requiring constant script updates and making data quality hard to keep consistent.
Technical Support Contact
Fix Unstable Video & Image Scraping with Scrapingbypass API Core Capabilities
Use Cloudflare handling and confirmed DataDome CAPTCHA support before parsing media listings. Validate asset identity, metadata and permitted usage so a verification screen is never stored as an asset result.
-
Bypass Verification for Stable Access
Automatically handles Cloudflare challenges and common blocks to reduce 403 errors and challenge pages, delivering a higher, more consistent scraping success rate.
-
Unified Cross-Platform Data Collection
Use one API workflow across multiple platforms and entry points. Reduce script differences and maintenance cost, and ship new scraping tasks faster with smoother iteration.
-
High Concurrency with Lightweight Bandwidth
Supports scalable concurrent request scheduling with efficient data transfer - ideal for batch media scraping and continuous content refresh pipelines.
-
Return Full Page HTML Source
Retrieve complete HTML and critical DOM structure for dynamic websites, minimizing missing fields and partial extraction caused by client-side rendering.

Use Cases
Designed for Websites That Require Cloudflare Bypass and Reliable Video & Image Asset Data Collection at Scale
Build a Cross-Platform Asset Library Faster
Batch collect media assets across multiple video and image sites with a unified scraping entry point and consistent content structure. Quickly create a searchable asset library with deduplication, tagging, categorization, and continuous updates to improve collaboration and reuse efficiency.
Track Trends and "Viral" Creative Patterns
Continuously scrape recommendation feeds and trending pages to monitor popularity changes, tag shifts, and content evolution. Identify repeatable headline and thumbnail patterns to support content strategy, topic selection, and campaign optimization.
Competitor Creative Monitoring & Benchmarking
Monitor competitor accounts and publishing cadence, capture newly released content, and generate comparison reports. Quickly understand their creative direction and asset density changes to plan your own publishing rhythm and differentiation strategy.
Create Training Data for Ad Creative Intelligence
Batch collect high-quality image and video samples to build training datasets for classification, clustering, and retrieval. Provide stable data sources for creative recommendation systems, similar-ad search, and style recognition models.
Optimize Search and Tag Taxonomy for Assets
Scrape titles, tags, and category metadata to build multi-dimensional indexing and a structured tagging system. Improve asset discovery and management efficiency - perfect for content platforms, creative libraries, and team asset operations.
Long-Term Incremental Sync & Backfill Crawling
For platforms with frequent updates and massive historical content, support incremental syncing by time windows and checkpoint-based backfilling. Avoid duplicate crawling and missing data gaps, keeping your scraping pipeline stable over the long run.
Scrapingbypass Onboarding Workflow
1.Create Your Account
Register a Scrapingbypass API account - Sign Up Now
Register a Scrapingbypass Proxy account - Sign Up Now
One account gives you API and proxy access. Log in within 30 days and open Trial Activity from the gift icon to claim trial credits and traffic.
2.Test with the Code Generator
Use the Code Generator to configure and test Cloudflare or DataDome requests. Both use the same integration logic and request code. Keep the proxy IP, cookies and session consistent.
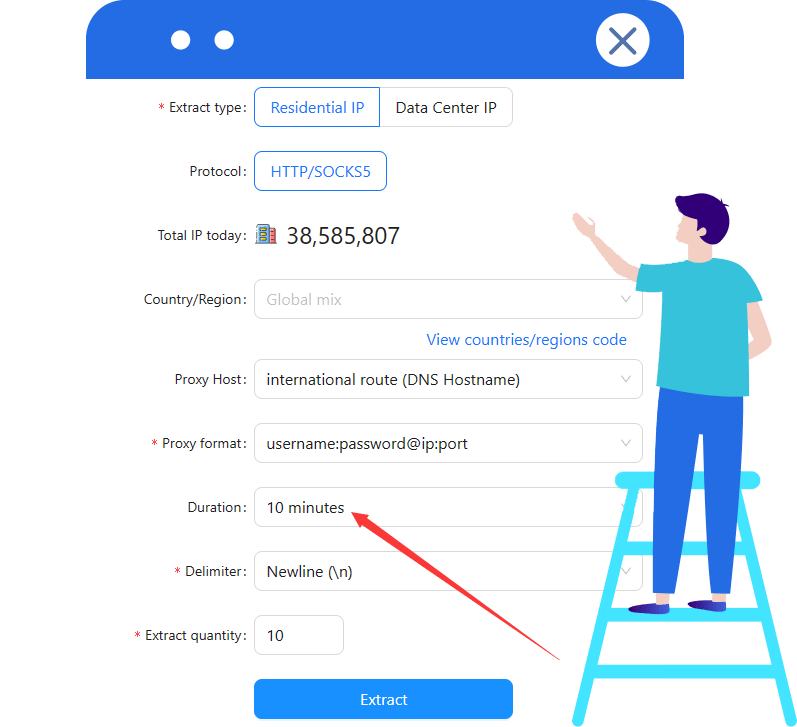
V1 includes a rotating proxy. V2(s) requires a stable proxy IP; configure a sticky session of at least 10 minutes when using Scrapingbypass rotating proxies.
For assistance, see the API documentation or contact Scrapingbypass Support.
3.Integrate the Scrapingbypass API
Integrate your tested request code into the application. Cloudflare and DataDome share the same API integration and call pattern. Validate response status and content before parsing, pagination or automation.
4.Select a Pricing Plan
After testing, choose a plan based on your usage. Cloudflare and DataDome share the same API credits, consumption rules and pricing. View Pricing
For proxy traffic, select a Rotating Datacenter or Rotating Residential proxy plan.
Cloudflare and DataDome challenge handling consume API credits; some workflows also need a proxy. API credits and proxy traffic are billed separately. A proxy connection does not replace CAPTCHA handling.

Scrapingbypass API Pricing
Test target compatibility, then choose an API plan for your workload
Each successful request costs 1 credit. Successful V2(s) verification costs 2 extra credits, not refunded if the later response fails. Proxy traffic is billed separately.
Basic Plan
-
$49
-
Credits:80000Validity:30 DaysSpeed:20 req/s
Standard Plan
-
$79
-
Credits:300000Validity:30 DaysSpeed:20 req/s
Advanced Plan
-
$129
-
Credits:1000000Validity:30 DaysSpeed:25 req/s
Pro Plan
-
$259
-
Credits:2200000Validity:30 DaysSpeed:25 req/s
Premium Plan
-
$489
-
Credits:4600000Validity:30 DaysSpeed:30 req/s
-
Best Value
Ultimate Plan
-
$1056
-
Credits:12000000Validity:30 DaysSpeed:30 req/s
Need more credits than the standard plans provide? Get a custom plan tailored to your workload Unlimited credits / Dedicated servers / Higher concurrency / Priority technical support
Contact Us for a Custom Plan Buy Rotating IPsFAQFrequently Asked Questions
Why is video/image content scraping so easy to get blocked?
Many content platforms run Cloudflare challenges and behavioral risk controls, plus dynamic rendering and rate-limiting. Traditional scrapers often trigger challenge pages or 403 blocks under high-frequency access, which makes collection unstable and lowers the overall success rate.
How does Scrapingbypass API handle Cloudflare verification and improve success rates?
Scrapingbypass API automatically handles Cloudflare-related challenges whenever possible, so your requests reach the real content page. It returns clean, parseable HTML source to reduce interference from challenge pages - making video/image data collection more continuous and reliable.
What if the page is dynamically rendered and I can't capture the content?
Many media sites load content via async endpoints, so a direct request may return only a "shell" HTML. Scrapingbypass API provides a more complete way to retrieve page source, reducing missing content and parsing failures - especially for list pages and detail pages.
How do I reduce rate-limit or ban risks when scraping at high concurrency?
Use layered scheduling: crawl list entries first, then pull detail pages by priority, with sensible concurrency and retry policies. Scrapingbypass API supports high concurrency and low-bandwidth workflows - ideal for stable batch runs and long-term continuous updates.
Site structures change often - how can I reduce ongoing maintenance?
Split your pipeline into three stages: "fetch HTML source -> parse structure -> validate data,"and add fallback logic for key selectors. With Scrapingbypass API reliably outputting page content, you can focus your effort on long-term parsing and cleaning maintenance.
What teams or use cases benefit most from video/image data scraping?
Teams building asset libraries, monitoring competitors, tracking trends, curating training datasets, or improving tag/search workflows. If your target sites use Cloudflare verification, Scrapingbypass API can significantly improve stability and efficiency.