
Why Scrapingbypass
Connect AI tools to reliable web fetch capabilities through MCP
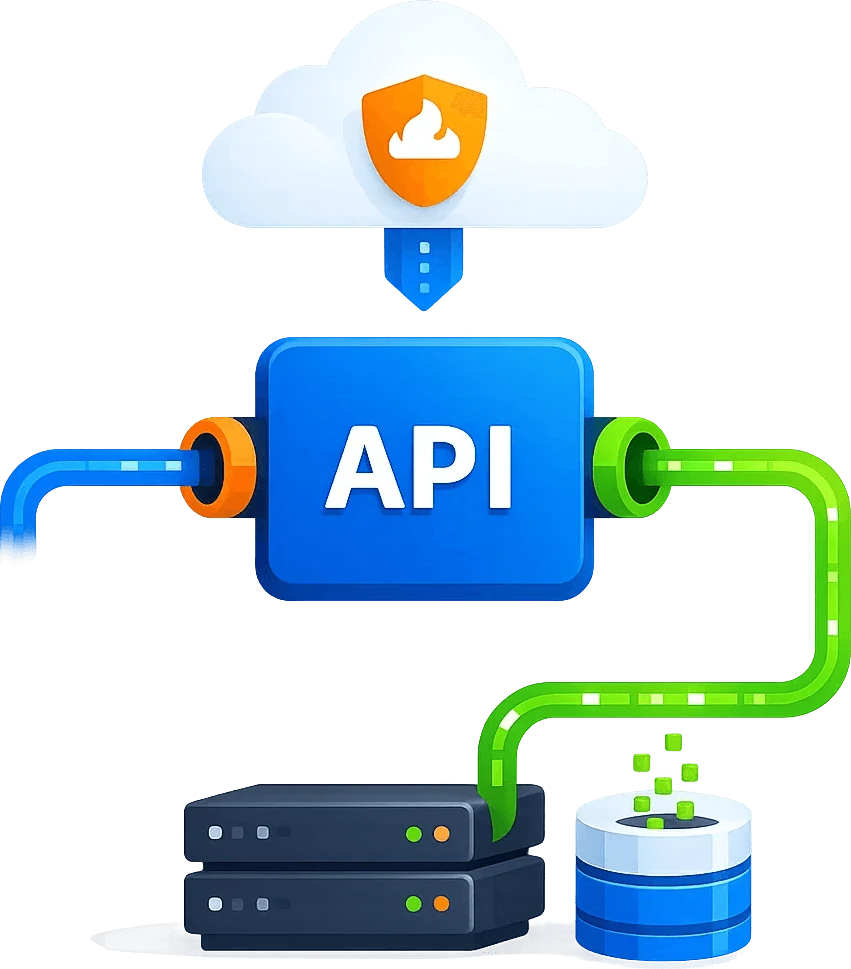
Wrap Scrapingbypass as an MCP web fetch tool for Claude, Cursor, Codex and internal agents. Expose regional access, rendering, screenshots and Markdown or JSON through a controlled interface. Keep Cloudflare handling and DataDome CAPTCHA solver integration in the access layer, and preserve verification errors rather than returning challenge text as source content.
Operational controls for teams
Use logs, status codes, sessions and retry settings to make MCP-based browsing safer to monitor, debug and scale across internal AI workflows.
Solution 2: proxy and session strategy
Choose dynamic residential IP, dynamic datacenter IP, rotation or sticky sessions by task type for long-term monitoring, multi-region verification and project isolation.
Cloudflare challenge handling
Connect AI tools to reliable web fetch capabilities through MCP
Scrapingbypass can be wrapped as an MCP web fetch server for Claude, Cursor, Codex and internal agent tools. It gives agents a controlled way to request live pages, choose regions, render dynamic content, capture screenshots and receive Markdown or JSON outputs.
Challenge pass stability 95%
Access-layer maintenance reduction 80%
Challenge handling
Keep Cloudflare handling and supported DataDome workflows in one access layer, with clear failure diagnostics.
IP rotation and sessions
Use rotating residential or datacenter IPs, sticky sessions and bounded retries for ongoing monitoring.
Regional access
Choose proxy locations by country, city and task.
Status logs and compliance
Keep status codes, screenshots and failure details for auditing.
Cloudflare / Turnstile / WAF
Let MCP tools really reach live pages protected by verification
Wrap Cloudflare handling, confirmed DataDome workflows, regional access and call logs in one MCP tool layer, with explicit response validation.
STEP 01
MCP tool functions
Expose web access as fetch, render, screenshot and extract tools.
STEP 02
Challenge handling
Handle Cloudflare verification and supported DataDome targets before tool calls return content; preserve diagnostics when access fails.
STEP 03
Client integration
Connect Cursor, Claude, Codex, Dify, Coze and internal agent workflows.
STEP 04
Call governance
Support allowlists, rate limits, logs and human confirmation to reduce automation risk.
Use Cases
Typical applications for MCP Web Fetch Server
For AI IDEs, agent platforms, internal automation tools and developer templates, covering business scenarios from one-off access to long-term monitoring.
Cursor / Claude Code calls
Build stable access, geo verification, screenshot evidence and structured results around Cursor / Claude Code calls, reducing manual checks and duplicate script maintenance.
AI Agent toolkits
Build stable access, geo verification, screenshot evidence and structured results around AI Agent toolkits, reducing manual checks and duplicate script maintenance.
Internal knowledge base ingestion
Build stable access, geo verification, screenshot evidence and structured results around Internal knowledge base ingestion, reducing manual checks and duplicate script maintenance.
Automated check tasks
Build stable access, geo verification, screenshot evidence and structured results around Automated check tasks, reducing manual checks and duplicate script maintenance.
Team access control
Build stable access, geo verification, screenshot evidence and structured results around Team access control, reducing manual checks and duplicate script maintenance.
Implementation steps
Connect the Scrapingbypass access layer in 4 steps
Start with one high-value page or task, validate access, then expand into scheduled workflows.
01. Define the access target
Confirm URL, region, frequency, output format and business boundary.
02. Choose an access strategy
Select API, rendering, screenshots, dynamic IP, sticky session or retry strategy.
03. Connect business systems
Send results to crawlers, AI agents, workflows, QA or internal monitoring systems.
04. Review and optimize
Track status codes, failure reasons, screenshots and logs to keep access stable.
FAQ
Common questions
How is this different from a normal proxy?
A normal proxy mainly provides an exit. Scrapingbypass focuses on the full access workflow: regional environment, dynamic pages, challenge handling, screenshots, structured output, retries and logs.
Is it suitable for non-developers and AI coding users?
Yes. Teams can build the business logic with templates, workflow tools or AI-generated code, then hand protected web access to the Scrapingbypass API.
How should compliance risk be controlled?
Use it for public data, authorized data and legitimate business workflows. Add domain allowlists, rate limits, task logs and human review where needed.