Publication data access across Cloudflare and DataDome verification
Keep permitted publication feeds, topic pages and chapter indexes in sync with a consistent fetch-and-validate process. Scrapingbypass handles Cloudflare challenges and offers a DataDome CAPTCHA solver workflow for supported sources. Confirm compatibility and content permissions, then validate article or chapter text before ingestion so verification pages do not enter your content index.
Start Free Trial API DOCs Code generator

Why News & Web Fiction Scraping Is Challenging
The Hardest Part of News & Web Fiction Scraping Is Getting Content Consistently
News sites and web fiction platforms update frequently, use complex page structures, and often run behind Cloudflare. During scraping, it's common to encounter verification loops, incomplete content, rate limiting, and dynamic rendering - leading to missing data and delayed synchronization.
-
Frequent Cloudflare Verification Blocks
5-second challenges, JavaScript checks, and Turnstile CAPTCHA can trigger repeatedly and break scraping scripts without warning.
-
Hard to Track Chapter Updates Continuously
Chapter lists change fast, causing missed updates, duplicate scraping, and unreliable long-term monitoring.
-
Dynamic Rendering Causes Missing Article Content
Asynchronous loading and pagination stitching may return empty or partial HTML, making structured parsing difficult.
-
High Concurrency Easily Triggers Anti-Bot Rules
Traffic spikes can lead to throttling and bans, resulting in unstable success rates and unpredictable performance.
Technical Support Contact
Build a Reliable Pipeline for News & Web Fiction Content Data Scraping with Scrapingbypass API
Use Cloudflare handling or a confirmed DataDome integration to separate verification from extraction. Check page identity, body text and update timestamps before indexing; access handling does not change the source publisher's licensing or permissions.
-
Automatically Bypass the JS Challenge
Skip the challenge logic. Unlock protected pages automatically and get the original HTML for higher scraping success.
-
Full Support for Cloudflare JS Challenge
Automatically handles Cloudflare JavaScript checks and redirect flows, minimizing script adaptation work and ongoing maintenance.
-
Turnstile-Compatible Scraping
Works with Turnstile and other bot-detection scenarios to reduce pipeline interruptions and keep your content updates running smoothly.
-
Stable High-Concurrency Output
Optimized for batch scraping at scale. Returns clean page source code that's ready for parsing and database ingestion.

Use Cases
Ideal for News & Web Fiction Content Scraping That Requires Bypassing Cloudflare and Other Verification Systems for Stable Data Collection
Trending News Aggregation & Duplicate Removal
Continuously scrape the latest updates across multiple sources, detect near-duplicates, and build a unified timeline and event database - powering search, recommendations, and real-time monitoring.
Incremental Sync for Fiction Catalogs & Chapters
Track continuous updates on index and chapter pages using timestamps or chapter IDs. Support incremental crawling with checkpoint resumes to prevent missing or duplicate data.
Structured Extraction for Content Detail Pages
Extract titles, content blocks, author metadata, publish time, and comment sections into a consistent schema - making indexing, retrieval, and content analytics far more efficient.
Leaderboard & Channel Update Monitoring
Schedule scraping for "Trending / Latest / Recommended / Category" entry pages to monitor ranking changes and update frequency - helping you capture content trends and platform signals.
Cross-Site Benchmarking & Republishing Tracking
Compare multiple versions of the same story or event across different sites, identify reposting paths, publishing delays, and rewrites - improving analysis accuracy and content intelligence.
Large-Scale Job Scheduling & Auto Retry Recovery
Run scraping tasks in queued batches with automatic retries and backfills on failures or blocks - keeping long-running data pipelines stable and preventing data gaps from growing.
Scrapingbypass Onboarding Workflow
1.Create Your Account
Register a Scrapingbypass API account - Sign Up Now
Register a Scrapingbypass Proxy account - Sign Up Now
One account gives you API and proxy access. Log in within 30 days and open Trial Activity from the gift icon to claim trial credits and traffic.
2.Test with the Code Generator
Enter your target URL in the Code Generator to test Cloudflare bypass. For DataDome-protected targets, review the DataDome CAPTCHA solver API workflow and confirm challenge compatibility with support before testing.
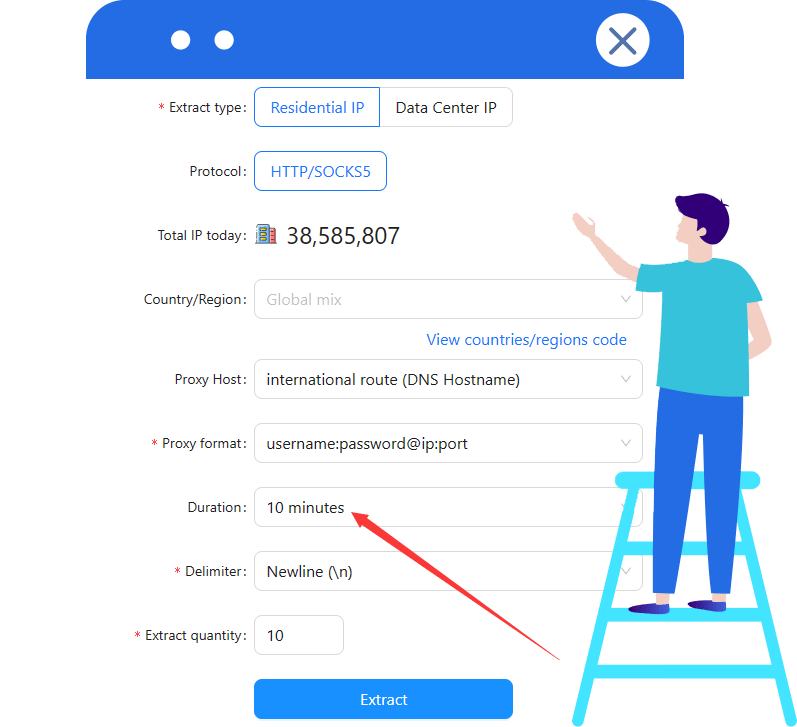
V1 includes a rotating proxy. V2 requires a stable proxy IP; configure a sticky session of at least 10 minutes when using Scrapingbypass rotating proxies.
For assistance, see the API documentation or contact Scrapingbypass Support.
3.Integrate the Scrapingbypass API
Integrate the confirmed Cloudflare or DataDome workflow into your application. Keep the proxy IP and session consistent, then validate the returned content before deployment.
4.Select a Pricing Plan
Choose a plan based on your usage - View Pricing
Choose a credit plan for Cloudflare JS Challenge. For DataDome CAPTCHA handling, confirm compatibility and pricing before purchasing.
For proxy traffic, select a Rotating Datacenter or Rotating Residential proxy plan.
Cloudflare bypass uses API credits and may require proxy support. For DataDome bypass, confirm supported targets and billing before choosing a plan. A proxy alone is not a CAPTCHA solver.
Scrapingbypass API Pricing
Handle Cloudflare challenges on 95%+ of websites and scrape data with confidence
Starting at $0.35 per 1,000 verifications. Failed requests are not charged. Each successful request uses 1 credit (Scrapingbypass V2 uses 3 credits).
Basic Plan
-
$49
-
Credits:80000Validity:30 DaysSpeed:20 req/s
Standard Plan
-
$79
-
Credits:300000Validity:30 DaysSpeed:20 req/s
Advanced Plan
-
$129
-
Credits:1000000Validity:30 DaysSpeed:25 req/s
Pro Plan
-
$259
-
Credits:2200000Validity:30 DaysSpeed:25 req/s
Premium Plan
-
$489
-
Credits:4600000Validity:30 DaysSpeed:30 req/s
-
Best Value
Ultimate Plan
-
$1056
-
Credits:12000000Validity:30 DaysSpeed:30 req/s
Need more credits than the standard plans provide? Get a custom plan tailored to your workload Unlimited credits / Dedicated servers / Higher concurrency / Priority technical support
Contact Us for a Custom Plan Buy Rotating IPsFAQFrequently Asked Questions
Why do news/fiction content scrapers often get stuck on Cloudflare verification?
News and fiction sites often enable Cloudflare protections like the 5-second check, JS Challenge, and Turnstile. These defenses are especially sensitive to high-frequency and batch requests, which can trigger challenges and blocks - breaking your scraping pipeline.
What types of Cloudflare challenges can Scrapingbypass API handle?
It supports common Cloudflare challenge flows such as the 5-second check (JS Challenge) and Turnstile. The API completes the unlock process automatically and returns page content you can parse - so your scraper needs far less custom handling.
After integrating Scrapingbypass API, what format do results come back in?
When the request succeeds, it typically returns the target page source (HTML), making it easy to extract姝f枃/content, parse chapters, deduplicate, and store the data on your backend.
How do you ensure stability for high-concurrency news/fiction content scraping?
Scrapingbypass API is built for batch scraping and supports concurrency to reduce verification-related failure spikes. For long-running crawlers, we recommend combining it with a task queue, retries, and incremental updates to keep refresh jobs continuous and reliable.
When tracking fiction chapter updates, how do you avoid missing or duplicating chapters?
Use "chapter number / update time" as your incremental key and persist checkpoints. If a request is blocked or fails, replay it from the queue with retries to keep the catalog-to-chapter chain complete and reduce data gaps.
What content scraping workflows is Scrapingbypass API best for?
It works well for structured scraping flows such as category lists, topic pages, article detail pages, table-of-contents pages, chapter pagination, and update feeds - especially when Cloudflare protections cause verification redirects and rate-limit issues.